
FYI, I use Softr as one of the main tools in this build, and I lead growth at Softr — so I want to be upfront. This newsletter isn’t sponsored, and I’m genuinely just sharing the tools I use for my own workflows.
Last week I got to have a fangirl moment demoing Softr and Claude MCP at Emily Kramer’s MKT1 Demo Day. During the event, I showed 3 examples of how we use the Claude Code MCP at Softr, but my personal favorite was a use case that is so incredibly useful it’s already making an impact at Softr.
Why we needed this
We’d been recording every sales call, but using them was a pain — if you wanted an insight, you had to open Fathom and read transcripts one by one. And as we started moving upmarket, I needed a way for the whole team to grab the takeaways they needed without waiting for a sales person to offer insights — basically, the kind of self-serve setup you’d normally need a sales intelligence tool for.
Here’s what’s in today’s article:
Why I chose to build this system vs an agent
How I scoped and built it (database, workflow, and Claude skill)
All of the learnings
Here’s everything my team can do now
Part 1: To build or not to build? — and what to build…?
Everyone is in their “builder” era right now. Love that.
But some things just aren’t worth building. And that’s okay.
I’ve been building custom tools and systems for years. I’ve also seen why they fail: they solve a problem that isn’t painful enough, they don’t work in production, or the solution never gets used by the actual team.
I’d also love if we collectively accepted that not every problem needs a Claude skill just because you learned how to make one.
Whenever I have an ‘idea’, here’s what I consider:
Is this a problem worth solving?
What does “solved” actually look like?
What’s the best way to solve it?
In my situation, the first two were pretty clear. I had no reliable way to look across sales calls without opening Fathom and reading transcripts. And like many SaaS AI features, Fathom AI leaves a lot to be desired…just saying.
Ideally, the system automatically pulls the same insights from every call, spot patterns across hundreds of calls, and makes it easy and self-serve for any teams than just my marketing team.
Why not just use a Claude skill?
A Claude skill was actually a perfectly good way to test aspects of the idea. I could give Claude a handful of transcripts, tell it what I wanted extracted, and see whether the output was useful.
But I needed the system to:
trigger on every call once it completed
extract the same insights every time
join the call to the right account and deal stage
store the results so they accumulated over time
let us sort, filter, and compare them
Also, if you’ve ever asked Claude to analyze a large set of calls, you’ve probably seen some of the tradeoffs:
It’s slow. Every question can mean working back through a lot of raw context.
It consumes a lot of context and usage. You keep loading much of the same source material again.
It’s harder to verify. When something looks wrong, figuring out where the mistake entered the process can be painful.
Can’t you just buy a Gong license?
Do I think you should always build instead of buy? Absolutely not. But in this case, building gave me something buying wouldn’t. Control.
Fathom is already great at capturing the raw material from the recorded calls. The part I wanted to own was what we extracted, how we structured it, which prompts we used, and how different teams could query it. Once the raw context already exists, that’s where building your own layer starts to make sense.
I’m a builder-first marketer. When I can, and when it makes sense, I build.
I hate sitting through sales demos. I hate asking for budget for software I’ll use 10% of. And I hate adding another tool to the stack when my team is already struggling to use or keep track of the ones we have.
Workflow vs agent vs skill? What’s the difference?
If the steps are known and repeatable, a workflow usually makes more sense. If the task is open-ended or one-off, an agent can be faster and more convenient.
A ton of use cases don’t need agents.
Workflow: follows a process you’ve already defined. The same steps run in the same order every time it’s triggered.
For example:
Fathom call ends → pull the transcript → match it to the Hubspot account → saves it to the database.
You can still use AI inside that workflow. You just call an LLM at the specific point where you need judgment.
Pull transcript → ask an LLM to identify the top 3 objections → save those objections inside of an objections field in the database.
Agent: You give it a goal plus guidelines or guardrails, and it decides what steps to take, what tools or data it needs, and what to do next based on what it finds.
Skill: You give the agent a reusable set of instructions for a specific type of task — basically, “when you’re looking for customer quotes, first narrow down to the calls that are actually relevant by checking the summary, then pull quotes from those.” The agent still has freedom in how it gets to the result.
I made the decision to use a workflow for the repeatable work, then use Claude on top of the structured data for the open-ended analysis.
Part 2: What I built
What I used to build this
Fathom → records sales calls
Softr Database → stores transcripts and structured insights
Softr Workflows → processes each call and enriches it with HubSpot + LLM data
HubSpot → source of truth for account and deal data
Claude + MCP → queries the stored data and finds patterns
How it works
When a Fathom recording finishes, it kicks off a Softr workflow:
Fathom call ends → identify the prospect from the transcript → match them to HubSpot → pull and clean the transcript → extract structured insights with an LLM → save the transcript and insights to a Softr Sales Call database.
That happens automatically for every call.
From there, anyone on the team can use Claude through MCP to query the database, look across calls, and pull the underlying transcript when they need more context or an exact quote.
From there, anyone on the team can use Claude through MCP to query the database. I created a skill that tells Claude how to query efficiently to avoid burning context and tokens on every run. For example, starting with the smaller structured fields and only pulling full transcripts when it actually needs them.
How I built it (the architecture)
Step 1: Scoping the MVP
Here’s a confession: I usually start building before I’ve fully planned things out.
My toxic trait is getting caught up in planning, so years ago I started forcing myself to jump into execution earlier. That doesn’t mean I don’t plan — I just do a quick write-up with the requirements: what’s the minimum solution I need, and what has to be true to know it’s successful?
I define my MVP by what I leave out. For every feature I could build or step I could add, I ask one question: do I need this to solve the most painful part of my workflow?
What it has to do (capabilities):
Run automatically after every sales call
Give the team an easy way to access the raw sales call transcripts
Extract the same set of insights from every call
Let me filter, group, and count those insights across calls, like pain points, competitors mentioned, and jobs to be done.
Let Claude find patterns and pull exact quotes without rereading every transcript
So I could ask things like:
“How many enterprise prospects mentioned permissions as a blocker?”
“Show me every call where someone compared us to Replit, with the exact quote.”
What good looks like (the success bar):
Cheap enough to run on every call
Accurate enough that I could trust the output
Easy to trace when something looked wrong
Useful to more than just the marketing team
Better results than simply connecting Claude directly to Fathom
For me, the MVP was done when the database and workflow were running reliably across roughly 80–100 calls, and Claude could query the stored data through MCP in a way that was actually useful.
Step 2: Designing the database
Note: I use Claude as my lab assistant. We work through the schema together. Once I give it a green light, Claude generates the fields in the Softr database via MCP.
Before I ran a single call, I decided how to store what I’d pull out. Same principle as always: don’t over-build.
There are two easy ways to fall into the over-build trap:
Extracting more fields than you actually need (to all my fellow ADHDers, I’m looking at you).
Adding more tables than necessary because you’re chasing the “perfect” relational setup.
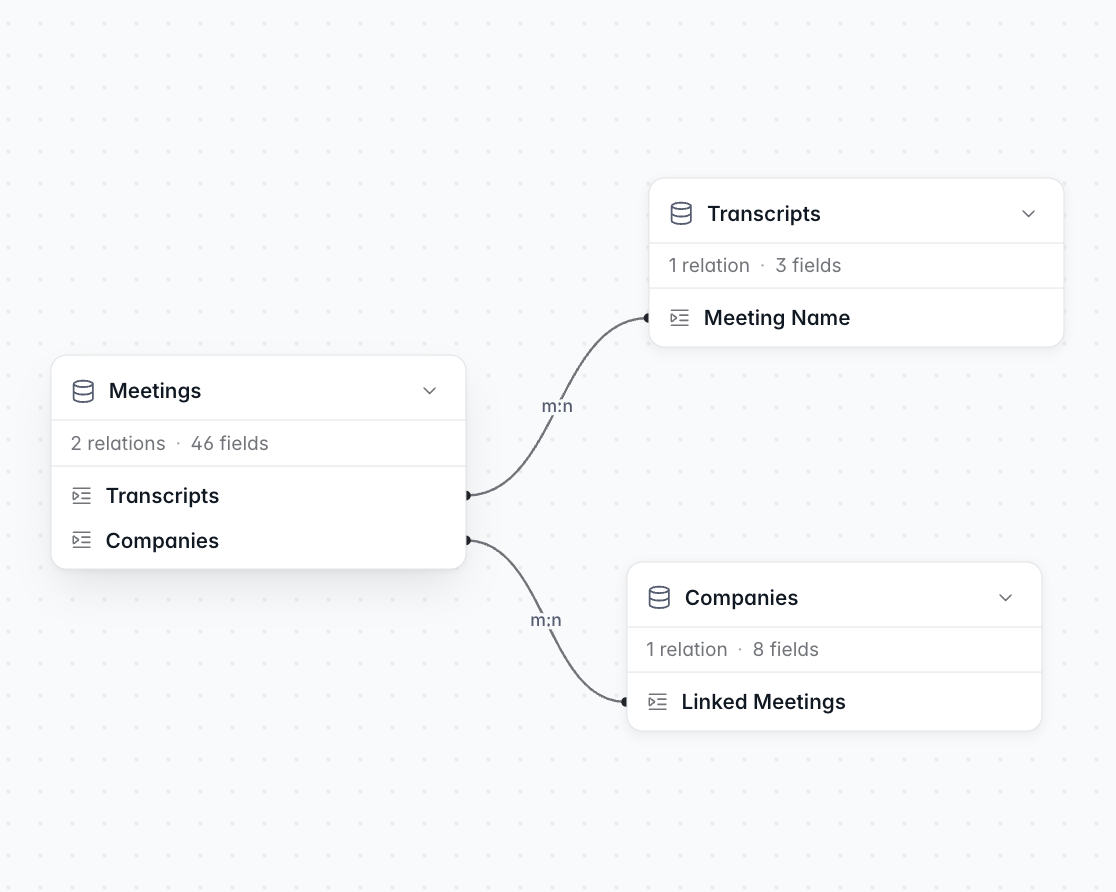
The database has 3 tables:
Meetings- one row per call, with the structured fields including: pain points, named competitors, objections, tech stack, and so on).
Transcripts- the raw transcript, linked back to the meeting.
Companies- one row per account, with fields like domain, size, industry, and a running count of how many calls we’ve had with them, plus links to the related meetings.

Decisions:
Keep transcripts separate. I almost stored the transcript and the extracted insights in the same table because it seemed simpler. But I query the Meetings table constantly, and I don’t need Claude pulling in a massive transcript every time. Keeping the structured fields lightweight means I only pull the transcript when I need more context or an exact quote.
Validate the extraction against a real call. Once I choose the fields I want to extract, I do a quick run-through with a single call (no, I don’t do it fully by hand—I do it with Claude directly). I read the transcript, check the extraction against it, and make sure it fits my framing. Don’t skip this—it’s how you keep your own marketing playbooks, frameworks, and judgment in the loop, instead of defaulting to whatever the model would produce.
Step 3: Building the workflow
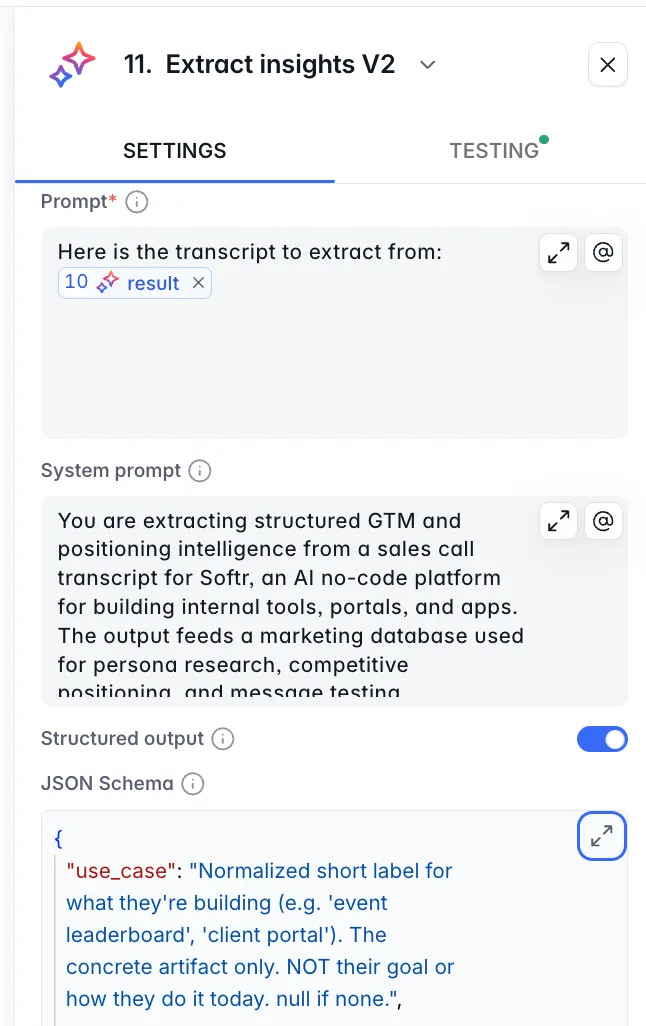
Instead of asking Claude to dig through a raw transcript and figure out the same things every time, the workflow does that work once when the call comes in.
When a call finishes, it:
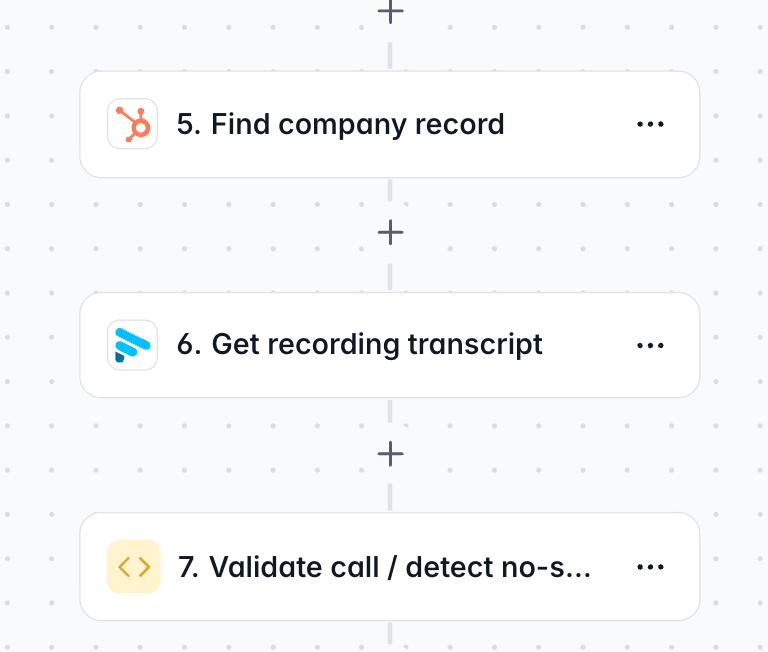
matches with the HubSpot contact
pulls the transcript and checks to make sure there isn’t a no show. Otherwise it would consume costs to run the workflow for no reason if there was no call.

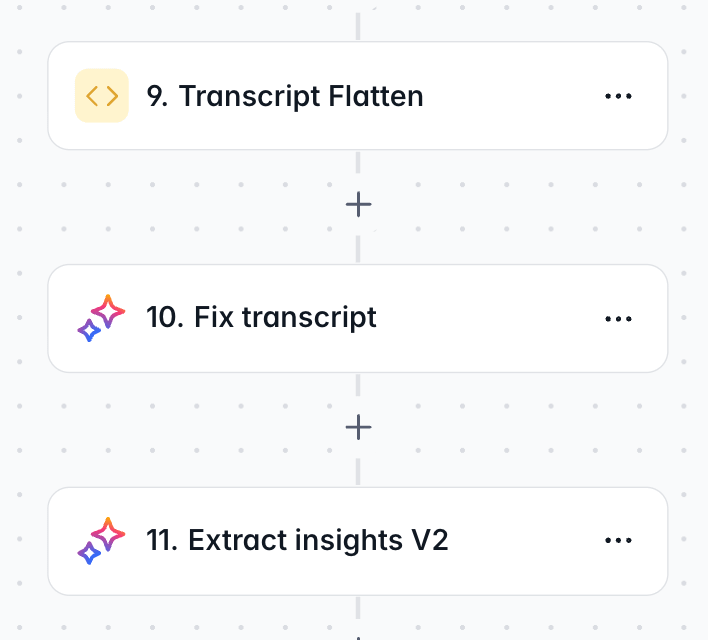
cleans the transcript (instead of passing the json array that isn’t needed).
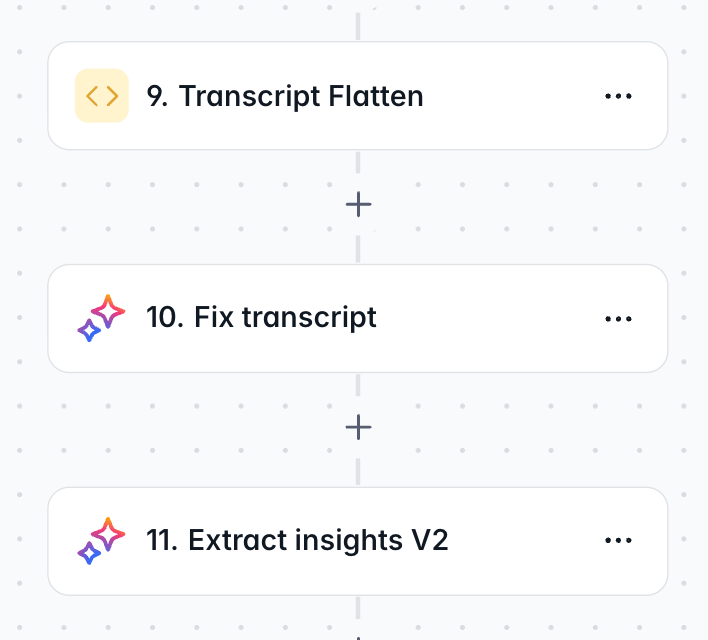
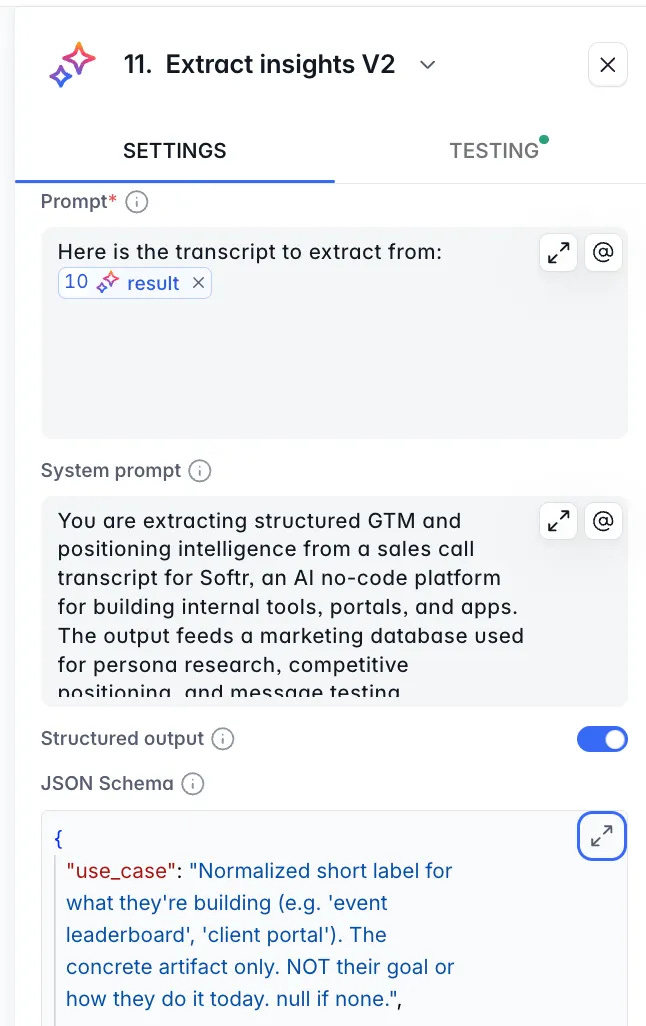
extracts the fields I know I’ll want again (ie competitors mentioned, JTBD, use cases, objections raised, etc).
stores everything in the database
That means Claude gets to start with a much cleaner dataset.
So if I ask:
“What objections are coming up most often in enterprise deals?”
Claude doesn’t need to reread 200 huge transcripts and rebuild the same context from scratch. It can start with the structured insights, spot the pattern, and only pull a transcript when it needs more context or an exact quote.
Part 3: What I learned
Use the cheapest model that’s good enough. I tested eight models for the extraction step and landed on Gemini 3 Flash as the cheapest one that still gave me output I trusted.
Transcript format made a surprisingly big difference. I added a workflow step to flatten the transcript into simple
Speaker: textinstead of passing JSON arrays. That cut my input token cost by about 48%, with no noticeable drop in output quality.When the output looks wrong, check the source data before blaming the model. Early on, some quotes were being attributed to the AE instead of the prospect. The model wasn’t really the problem, the transcript itself was messy. I added a cheap cleanup step before extraction inside of the workflow and that fixed a lot of it.
Fix the prompt before upgrading the model. When a field was inconsistent, making the definition clearer usually helped more than moving to a more expensive model. I was still able to extract all 20 fields in a single step without turning the prompt into a giant list of edge cases.
Add fields one at a time. I added one field, tested it against a real call, made sure it worked, then moved to the next. It’s slower at the beginning, but much easier than trying to figure out which part of a giant JSON response is going wrong.
What can I (and my team) do now that we couldn’t do before
I turned our pile of dusty sales calls into insights we can actually mine and use.
Jump into Claude and run a skill that gives us new insights by persona around pain points, objections, and competitors.
Use a Claude skill to update landing pages with new messaging based on insights from the ongoing database.
Claude suggests new ad angles and copy in customer language (based on real extracted quotes, not Claude’s summarized quotes).
All teams can easily access transcripts without having to dig through fathom.
Our product team gets a new pipeline of feature requests they can prioritize based on ICP fit.
We can give permissioned MCP access to external agencies to grab insights that help them do their own work.
Resources
How to build a database on Softr: https://docs.softr.io/core-concepts-overview/create-a-database.
Using the Softr MCP: https://docs.softr.io/app-mcp-server#app-mcp-server
Get Softr for free
Love this - and owning "planning" as your toxic trait. Too many people get stuck there, so kudos for getting out of your comfort zone to execute!